Transcribed
Course 40 - Web Scraping with Python | Episode 28: Base and Generic Crawling Classes
Aug 8, 2026 ·
13m 7s
Download and listen anywhere
Download your favorite episodes and enjoy them, wherever you are! Sign up or log in now to access offline listening.
Course 40 - Web Scraping with Python | Episode 28: Base and Generic Crawling Classes
This automatic transcript is brought to you by
Sounder.AI
This is an automatically generated transcript. Please note that complete accuracy is not guaranteed.
Description
This episode is essentially about how Scrapy structures crawling logic through different spider types, and when to use each one depending on the scale and structure of the target site.Here’s...
show more
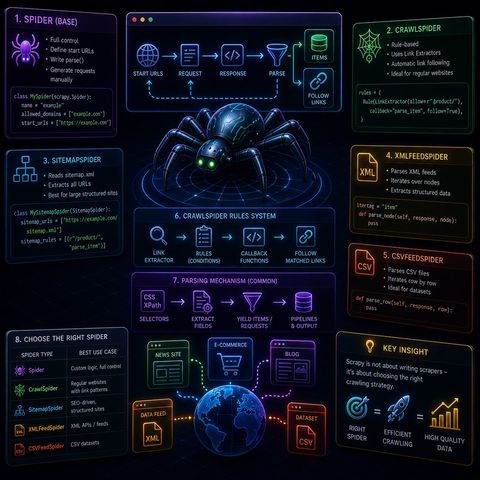
This episode is essentially about how Scrapy structures crawling logic through different spider types, and when to use each one depending on the scale and structure of the target site.Here’s the clean, structured breakdown:🕷️ Scrapy Spiders — Architecture & Types1. What a Spider Actually IsA Scrapy spider is a Python class that defines:
You can listen and download our episodes for free on more than 10 different platforms:
https://linktr.ee/cybercode_academy
Get the books of the CyberCode Academy podcast:
📚 The book series: 416 lessons, 12 books, hundreds of original diagrams: security, networking and programming.
https://cybercodeacademy.gumroad.com/
show less
- Where to crawl (scoping)
- How to crawl (link following rules)
- What to extract (parsing logic)
- name → identifier for the spider
- allowed_domains → restricts crawling scope
- start_urls → initial entry points
- Scrapy sends requests automatically via start_requests
- Responses are passed to parse()
- You manually extract data + generate next requests
- Uses Link Extractors
- Uses Rules
- Automatically follows links that match conditions
- “Follow all product links”
- “Ignore login pages”
- “Only crawl category pages”
- /sitemap.xml
- Reads sitemap URLs
- Extracts all listed links automatically
- Crawls them without link discovery logic
- Large structured websites
- SEO-friendly sites
- E-commerce catalogs
- Iterates over XML nodes
- Extracts structured fields
- Iterates row-by-row through CSV files
- Link Extractor → finds links on pages
- Rules → define which links to follow
- Callback functions → process matched pages
- Follow category pages
- Extract product pages only
- Ignore pagination or ads
- Extracting structured fields (title, price, etc.)
- Using XPath or CSS selectors
- Yielding items or new requests
You can listen and download our episodes for free on more than 10 different platforms:
https://linktr.ee/cybercode_academy
Get the books of the CyberCode Academy podcast:
📚 The book series: 416 lessons, 12 books, hundreds of original diagrams: security, networking and programming.
https://cybercodeacademy.gumroad.com/
Information

Copyright 2026 - Spreaker Inc. an iHeartMedia Company

Comments