Transcribed
Course 40 - Web Scraping with Python | Episode 26: Framework Overview and Core Architecture
Aug 6, 2026 ·
22m
Download and listen anywhere
Download your favorite episodes and enjoy them, wherever you are! Sign up or log in now to access offline listening.
Course 40 - Web Scraping with Python | Episode 26: Framework Overview and Core Architecture
This automatic transcript is brought to you by
Sounder.AI
This is an automatically generated transcript. Please note that complete accuracy is not guaranteed.
Description
In this lesson, you’ll learn about: what makes Scrapy a framework (not just a library), how its asynchronous engine works, and how its core components cooperate to deliver fast, scalable...
show more
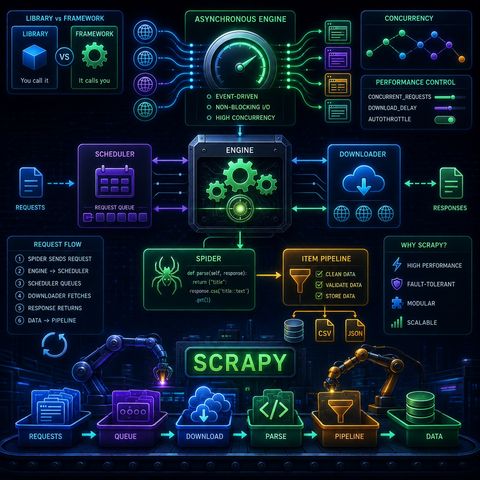
In this lesson, you’ll learn about: what makes Scrapy a framework (not just a library), how its asynchronous engine works, and how its core components cooperate to deliver fast, scalable web scraping1. Library vs Framework (Core Concept)🔹 Who Controls the Flow?🔹 Key Difference
Scrapy is a framework because it controls execution (Inversion of Control)2. Asynchronous Power (Why Scrapy is Fast)🔹 Event-Driven Architecture🔹 What Makes It Powerful
Scrapy doesn’t scrape pages one-by-one—it handles many at once3. Scrapy Architecture (Big Picture)🔹 How Components Interact4. Core Components Explained🔹 1. Engine
Each component has one responsibility → modular & scalable5. Request Flow (Step-by-Step)
Speed without control = getting blocked7. Why Scrapy is Production-Ready
You can listen and download our episodes for free on more than 10 different platforms:
https://linktr.ee/cybercode_academy
show less
- Library → you call it when needed
- Framework → it calls your code
Scrapy is a framework because it controls execution (Inversion of Control)2. Asynchronous Power (Why Scrapy is Fast)🔹 Event-Driven Architecture🔹 What Makes It Powerful
- Uses event-driven networking
- Handles many requests simultaneously
- Doesn’t wait (non-blocking I/O)
Scrapy doesn’t scrape pages one-by-one—it handles many at once3. Scrapy Architecture (Big Picture)🔹 How Components Interact4. Core Components Explained🔹 1. Engine
- Central controller
- Manages request/response flow
- Your custom logic
- Extract data from responses
- Queues requests
- Decides what to crawl next
- Sends HTTP requests
- Retrieves web pages
- Cleans data
- Validates data
- Saves data (DB, CSV, etc.)
Each component has one responsibility → modular & scalable5. Request Flow (Step-by-Step)
- Spider sends request
- Engine forwards to Scheduler
- Scheduler queues it
- Downloader fetches page
- Response returns to Spider
- Data sent to Pipeline
- Limit concurrent requests
- Control request delays
- Enable auto-throttling
Speed without control = getting blocked7. Why Scrapy is Production-Ready
- ⚡ High performance (async)
- 🔄 Fault-tolerant (handles failures)
- 🧱 Modular architecture
- 🎯 Precise data pipelines
- 🏭 Engine → manager
- 🕷 Spider → worker extracting data
- 📦 Scheduler → task queue
- 🌐 Downloader → fetcher
- 🧹 Pipeline → cleaner & packager
- Massive speed via asynchronous processing
- Clean architecture for scaling
- Full control over performance and behavior
You can listen and download our episodes for free on more than 10 different platforms:
https://linktr.ee/cybercode_academy
Information

Copyright 2026 - Spreaker Inc. an iHeartMedia Company

Comments